DeepSeek V4.1 Flash: 552B parameters, 8B awake
Carousel · 9 slides
DeepSeek V4.1 Flash: 552B parameters, but only 8B active per token while reading (16B while writing).
→ 384 experts per layer, 6 fire per token
→ KV cache: 890 bytes per token, 437× smaller than DeepSeek V1
→ 1M-token context, trained on 45T tokens
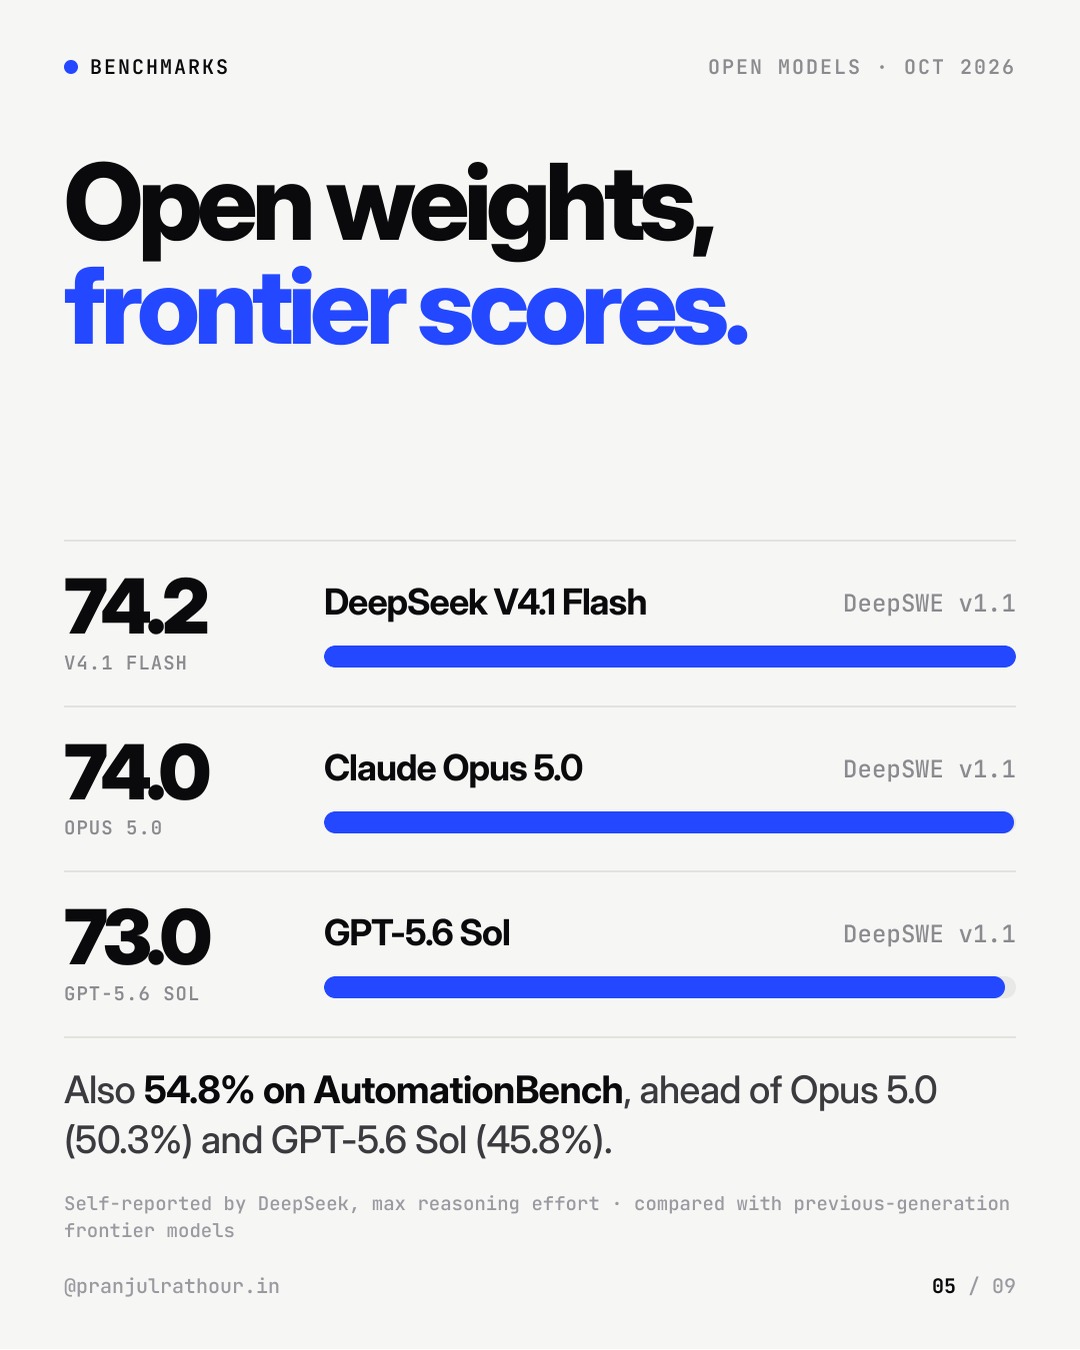
→ Self-reported 74.2% on DeepSWE v1.1, level with Opus 5.0 and GPT-5.6 Sol
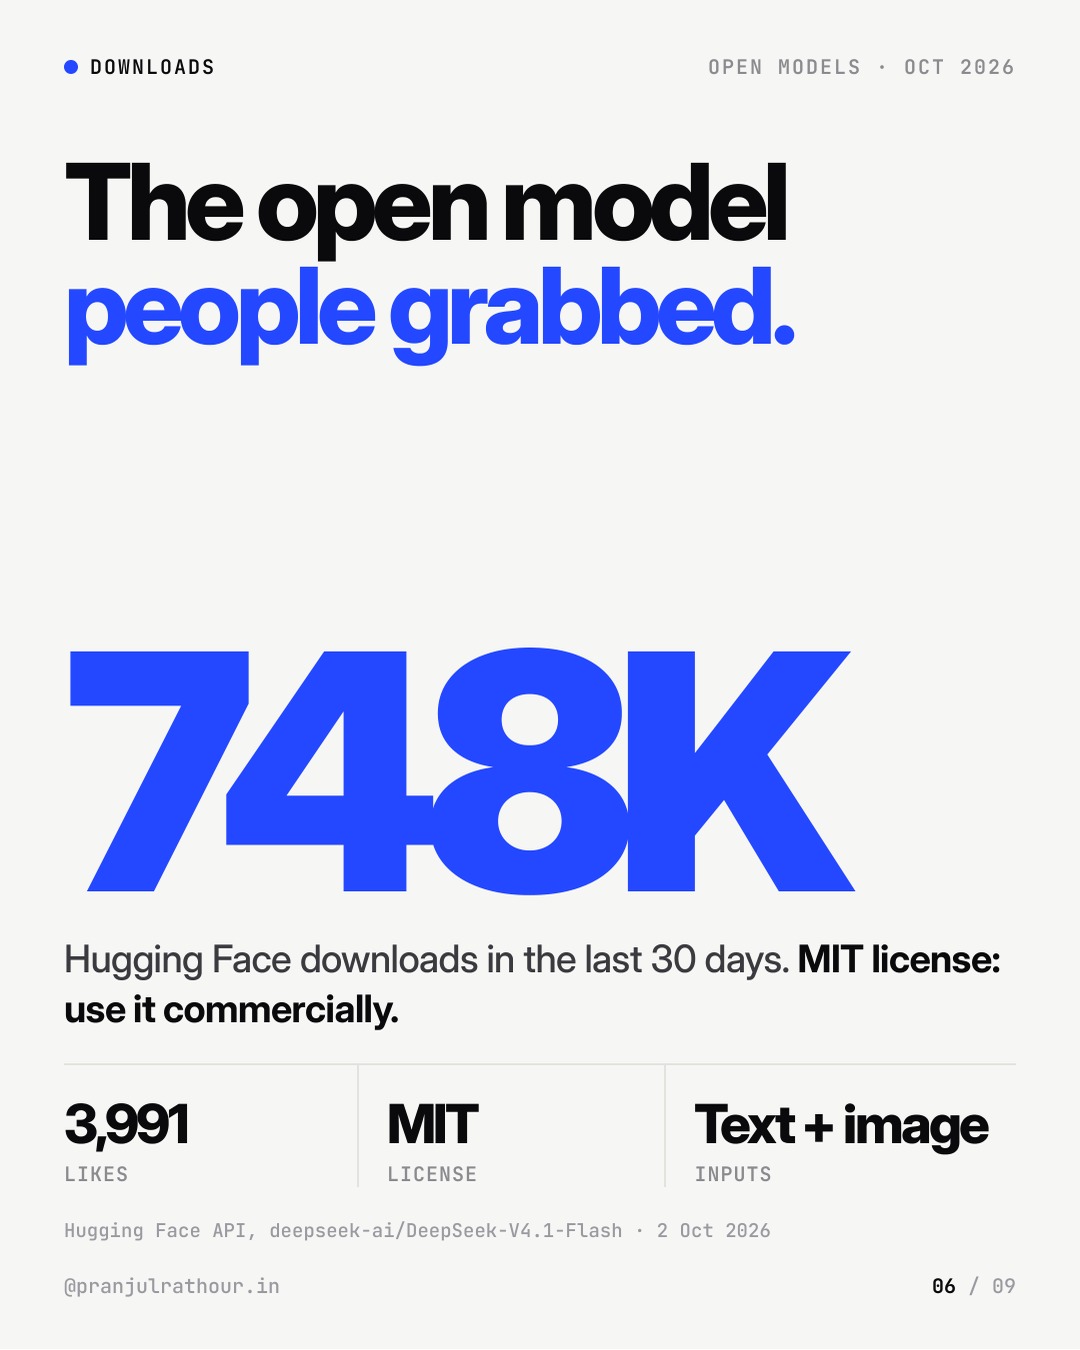
→ MIT license, 748K downloads in 30 days
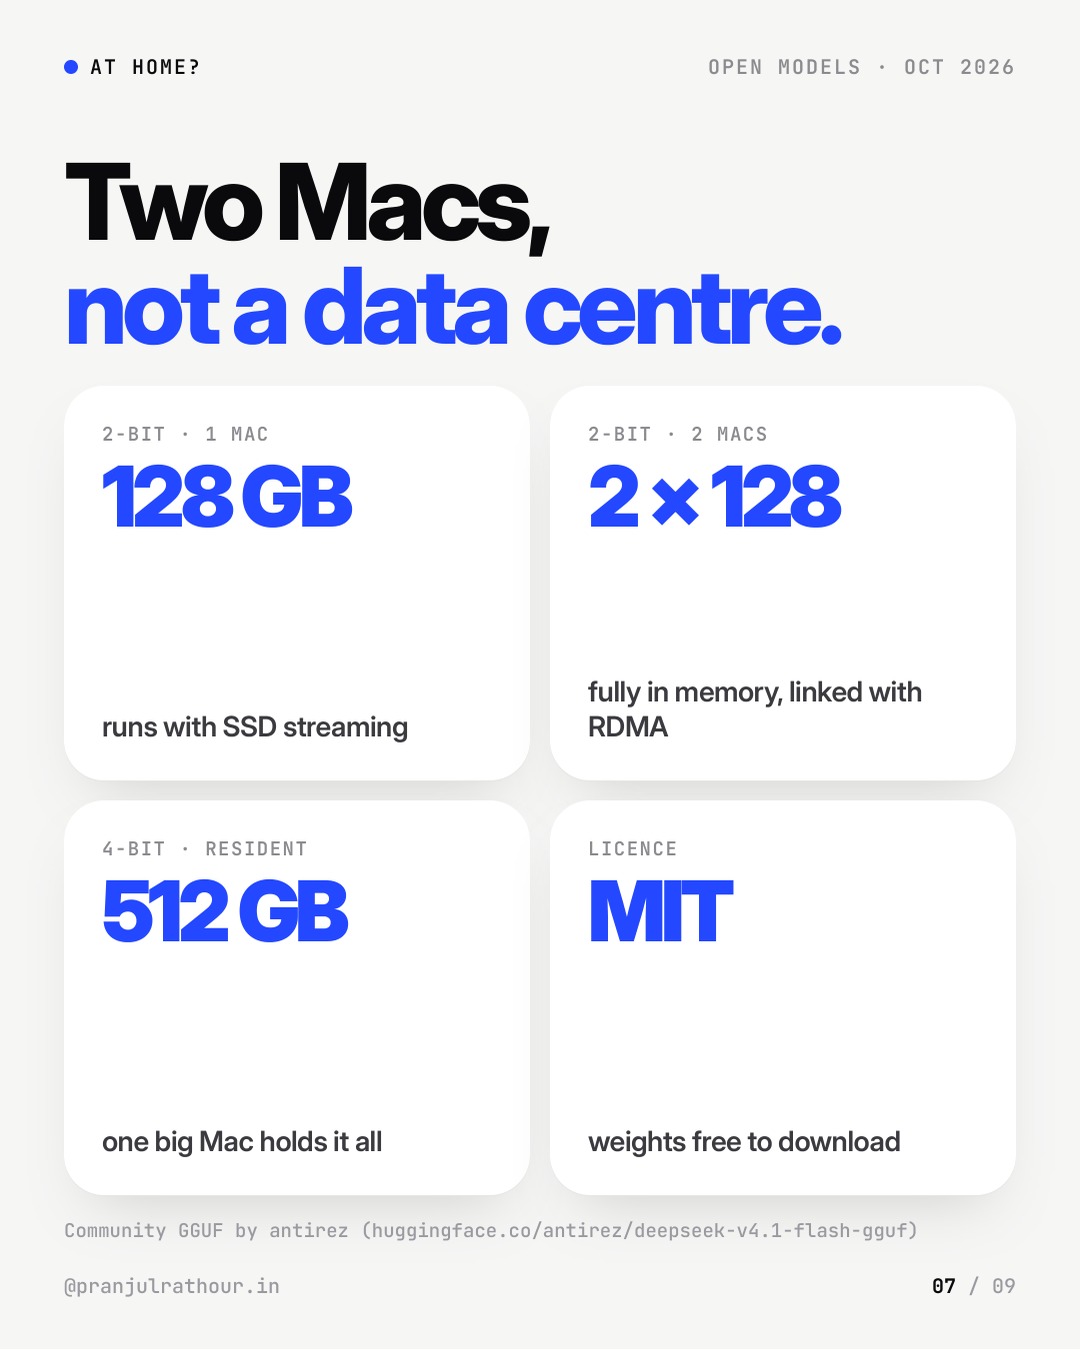
And the 2-bit build runs fully in memory on two 128 GB Macs.
I'm Pranjul Rathour, GenAI engineer from Kanpur. Want me to judge your hackathon or speak at your college? pranjulrathour.scult.in/invite
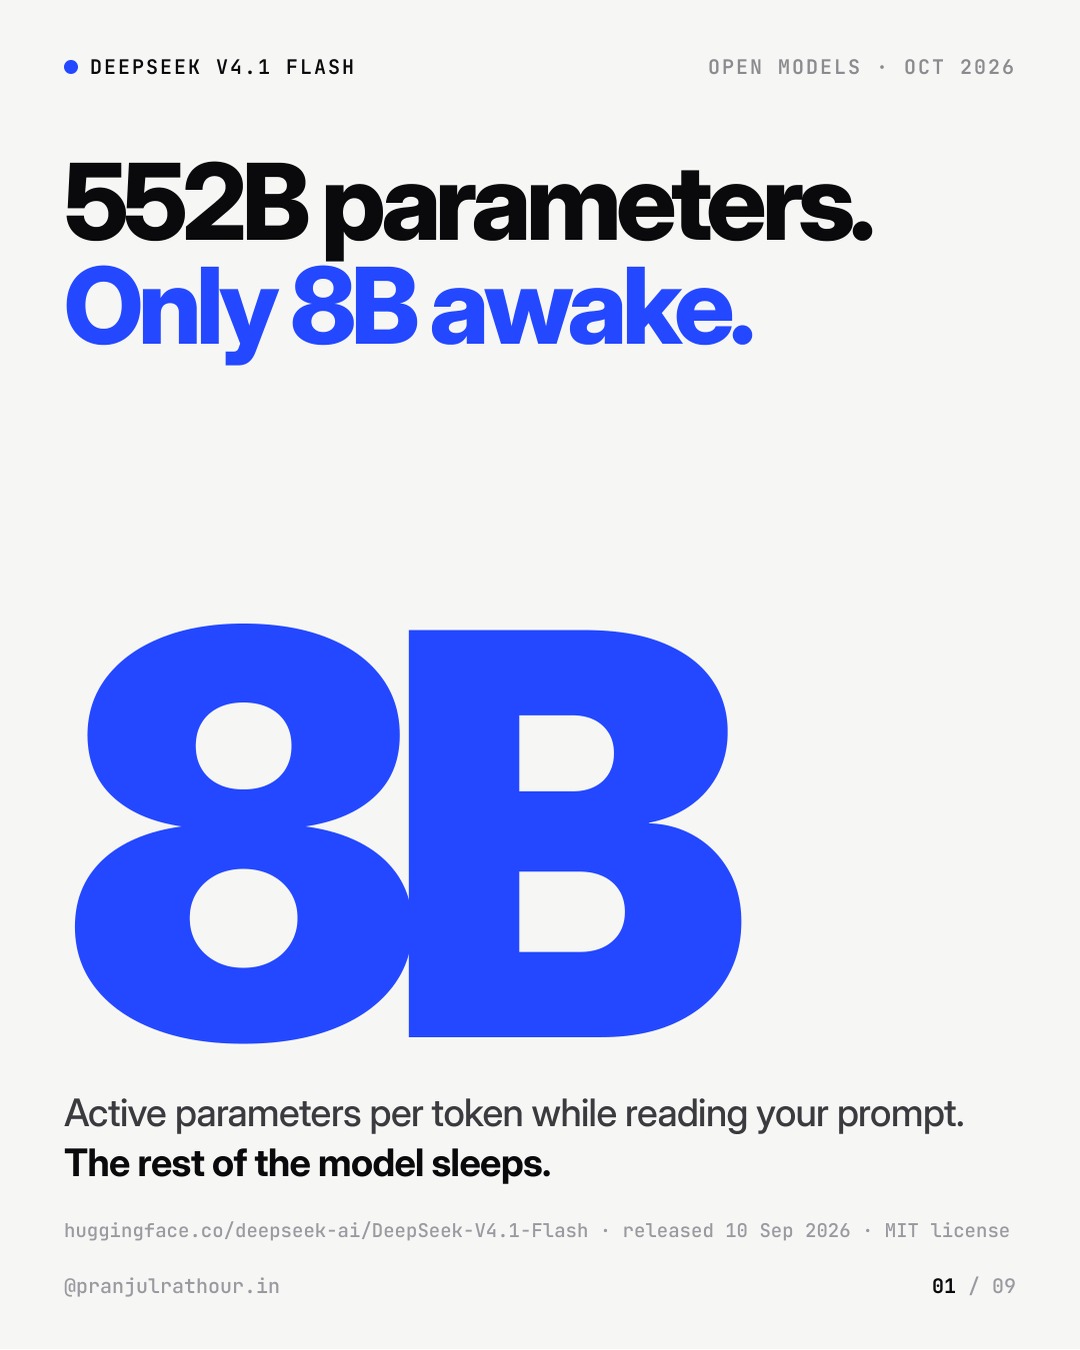
Slide 1 of 9
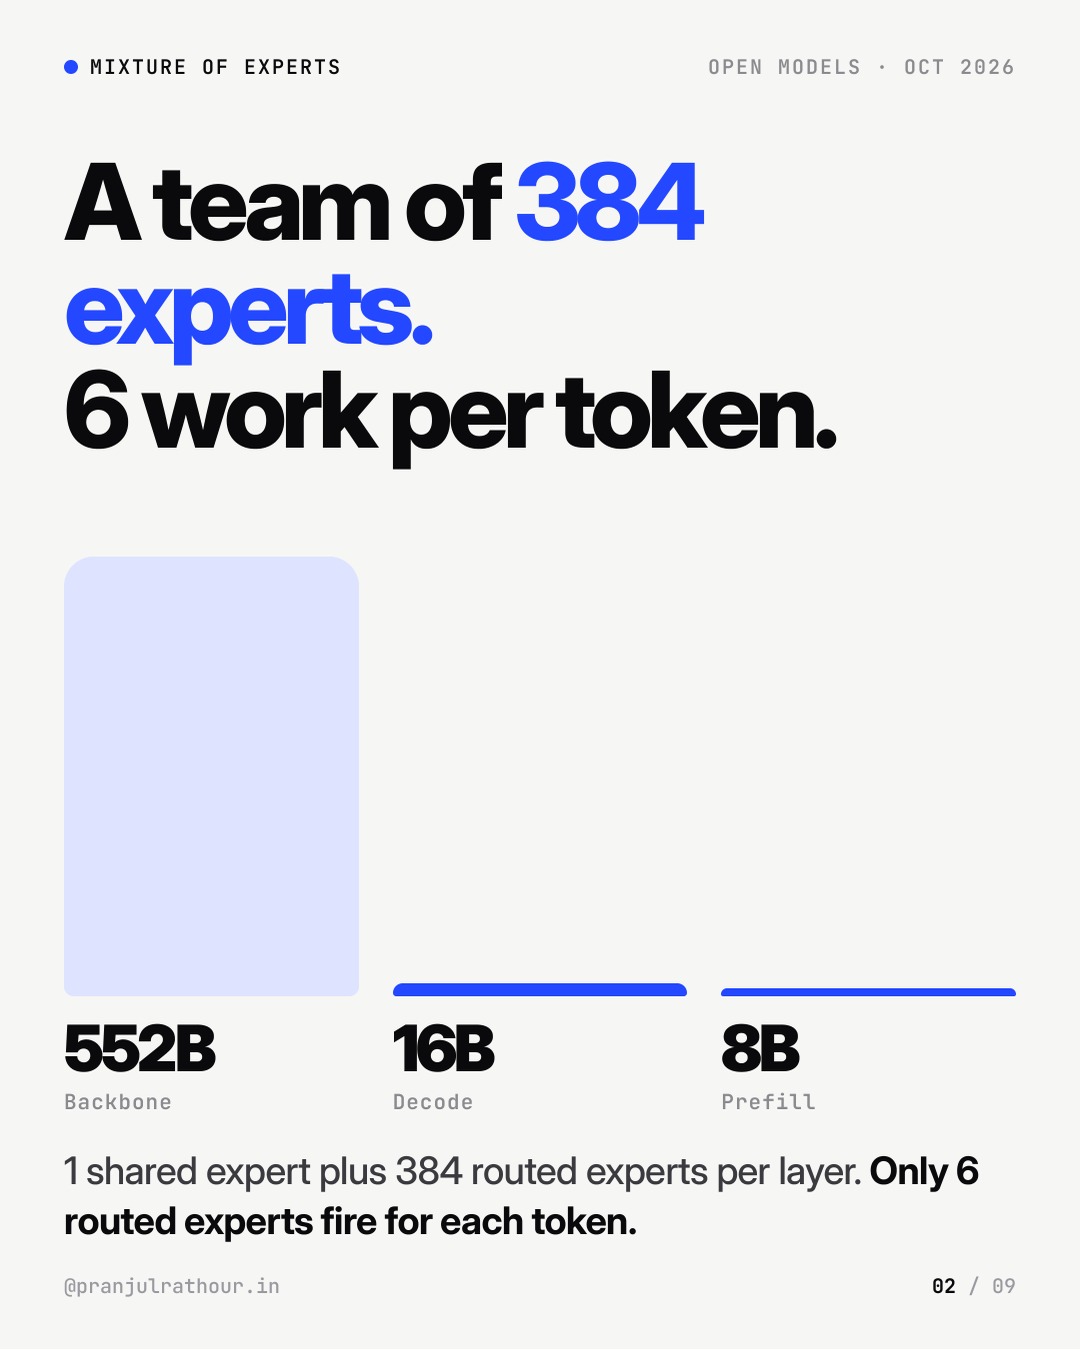
Slide 2 of 9
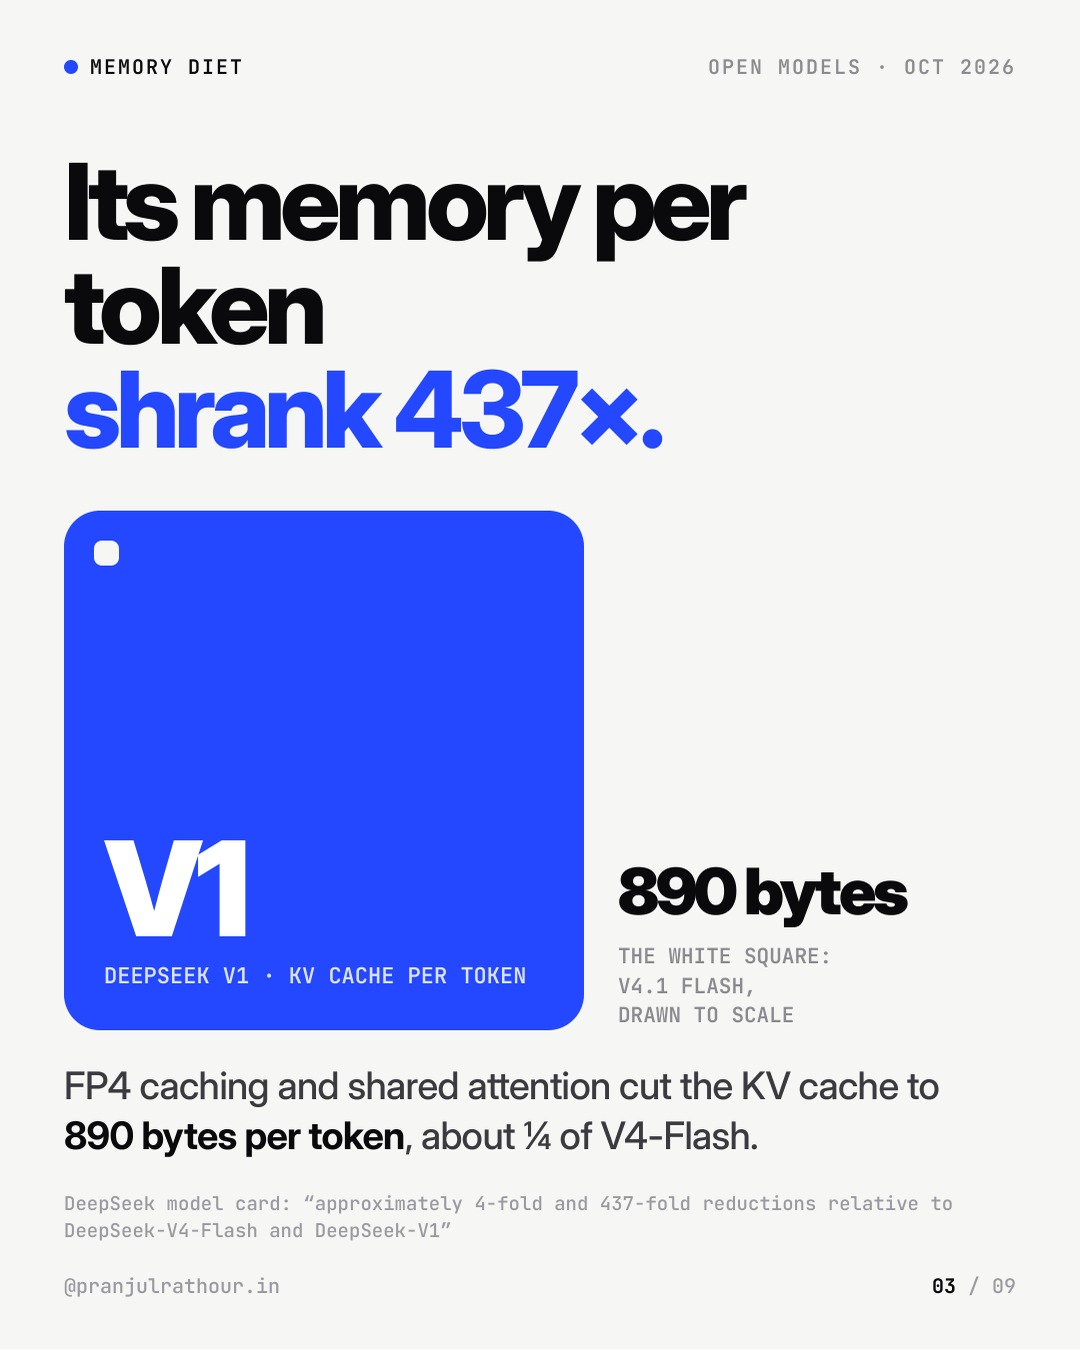
Slide 3 of 9
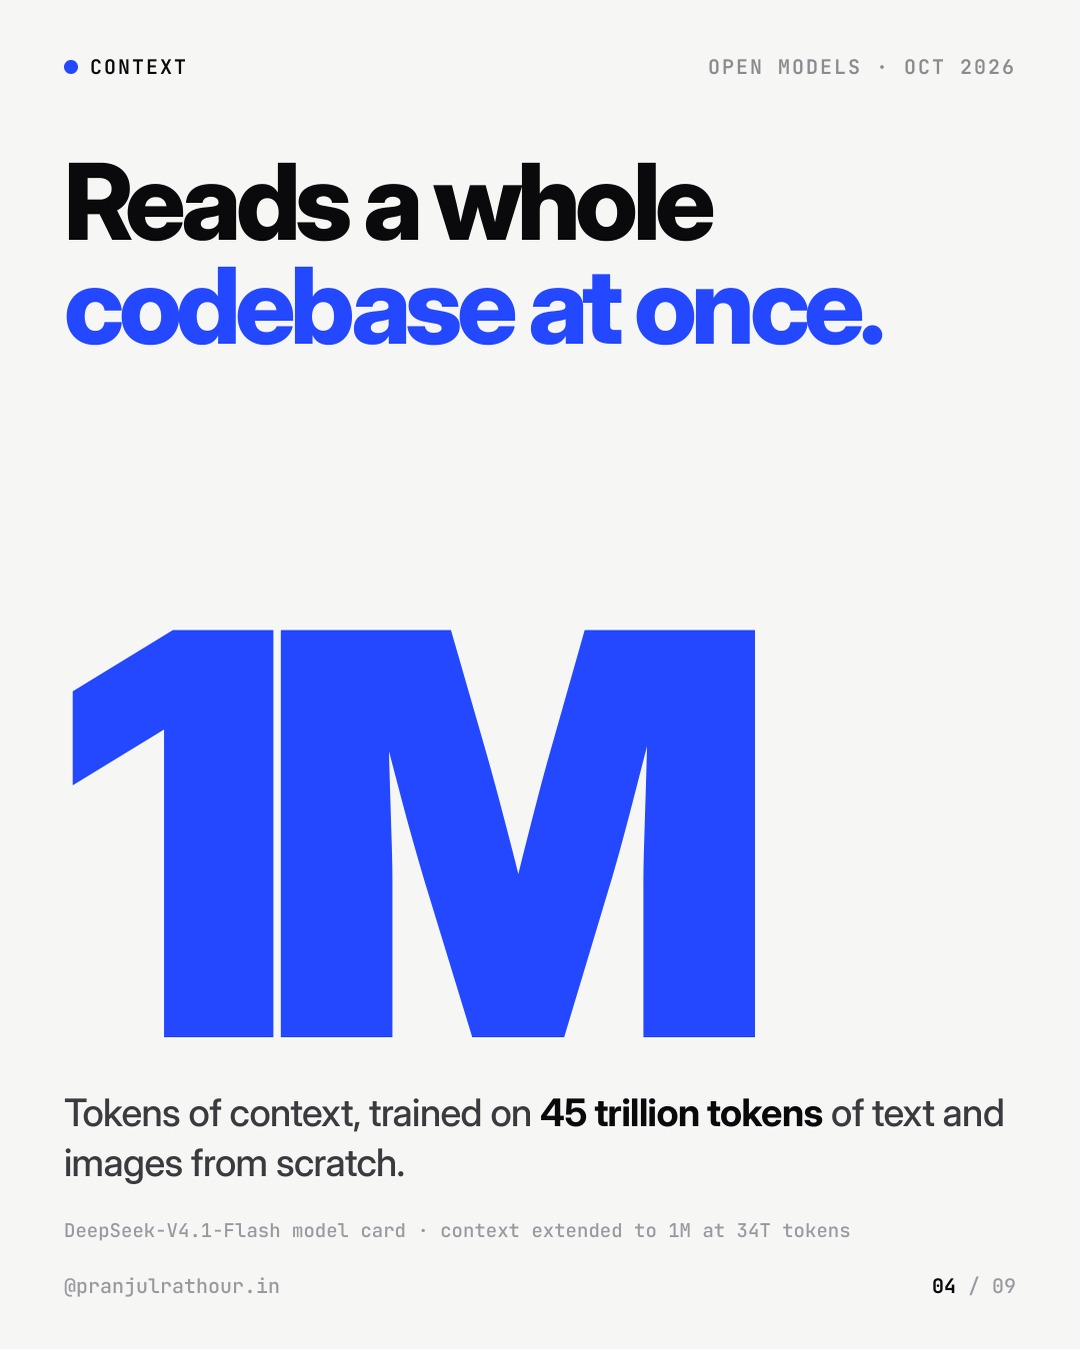
Slide 4 of 9
Slide 5 of 9
Slide 6 of 9
Slide 7 of 9
Slide 8 of 9
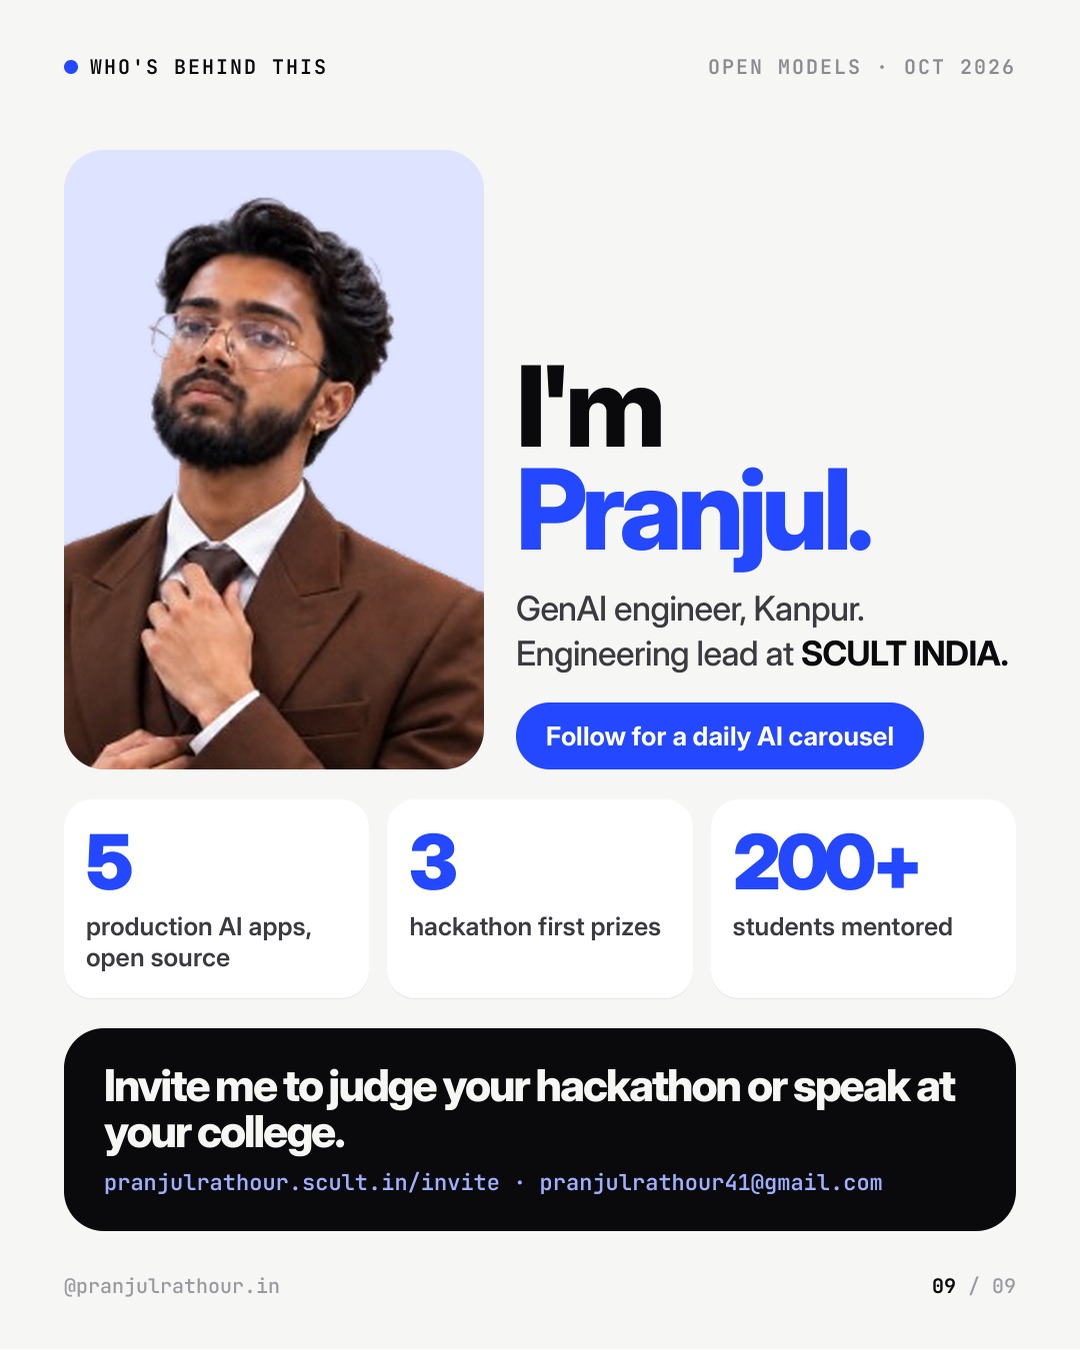
Slide 9 of 9
 | Pranjul Rathour GenAI engineer, Kanpur · 3x first-prize hackathon winner · campus mentor I ship production RAG pipelines, fine-tune LLMs and build agentic AI products end to end. I lead engineering at SCULT INDIA for a 14-member team and have mentored 200+ students through TechVerse Enclave. Open to: GenAI roles, hackathon judging, mentorship sessions and guest talks at colleges. Email: pranjulrathour41@gmail.com |
On stage, at hackathons and on campus
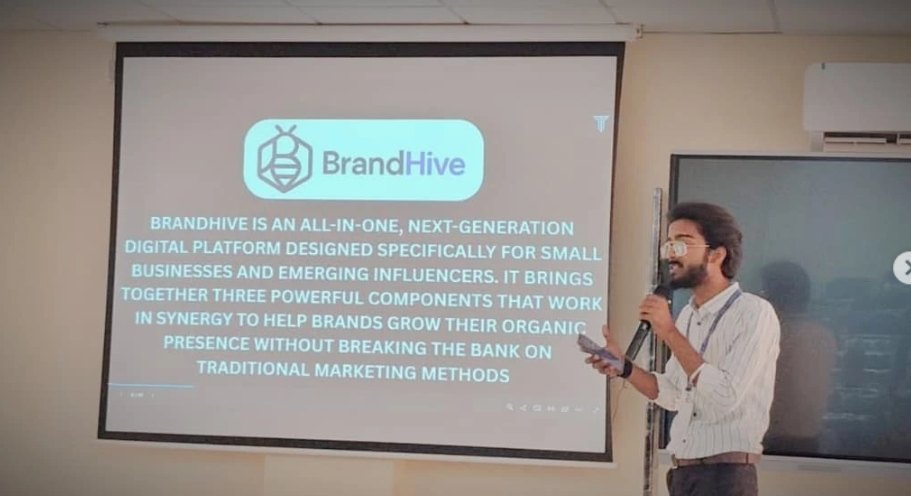 Presenting BrandHive | 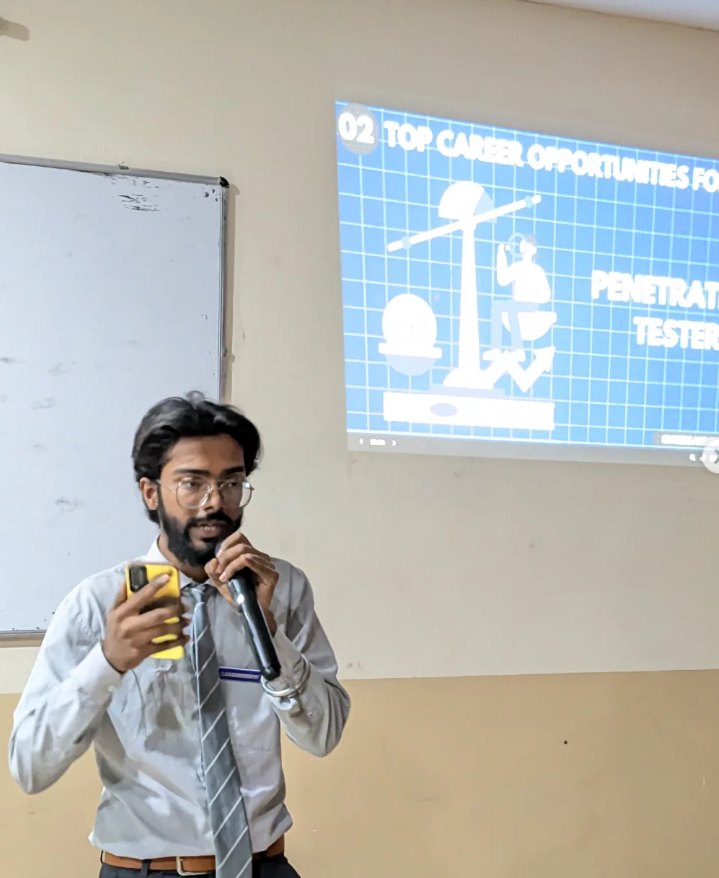 A career session for students |  Presenting to a room |


Comments
Post a Comment