Ten fine-tuning mistakes I see students make (and made myself)
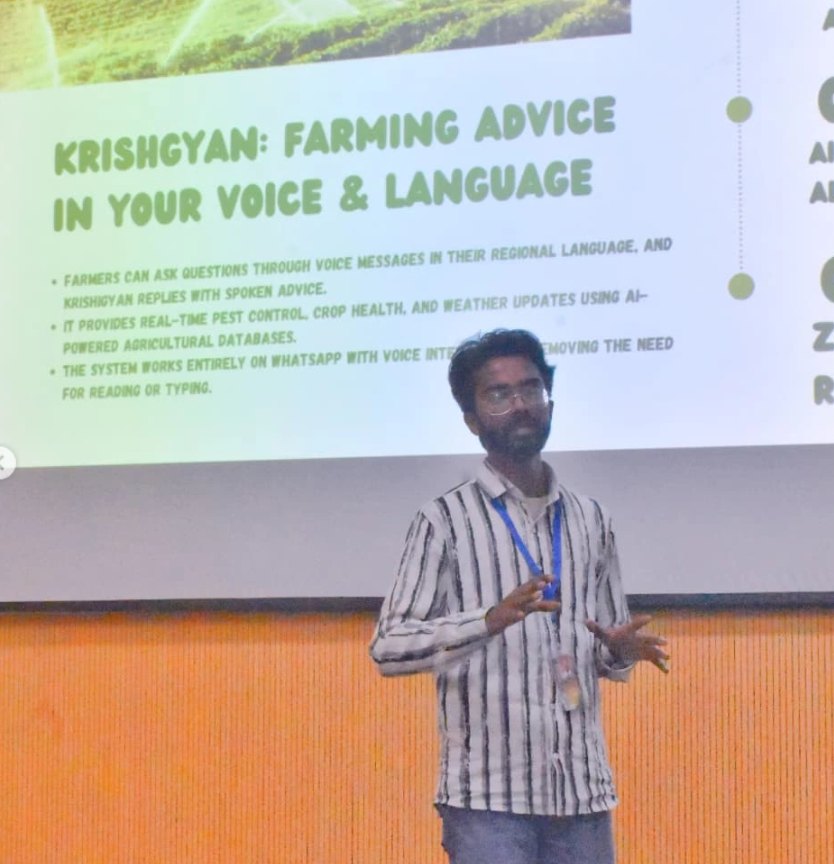
Presenting KrishGyan, farming advice in your voice and language
Originally published at https://pranjulrathour.scult.in/blog/fine-tuning-mistakes-students-make. That copy is the canonical version and gets updates first.
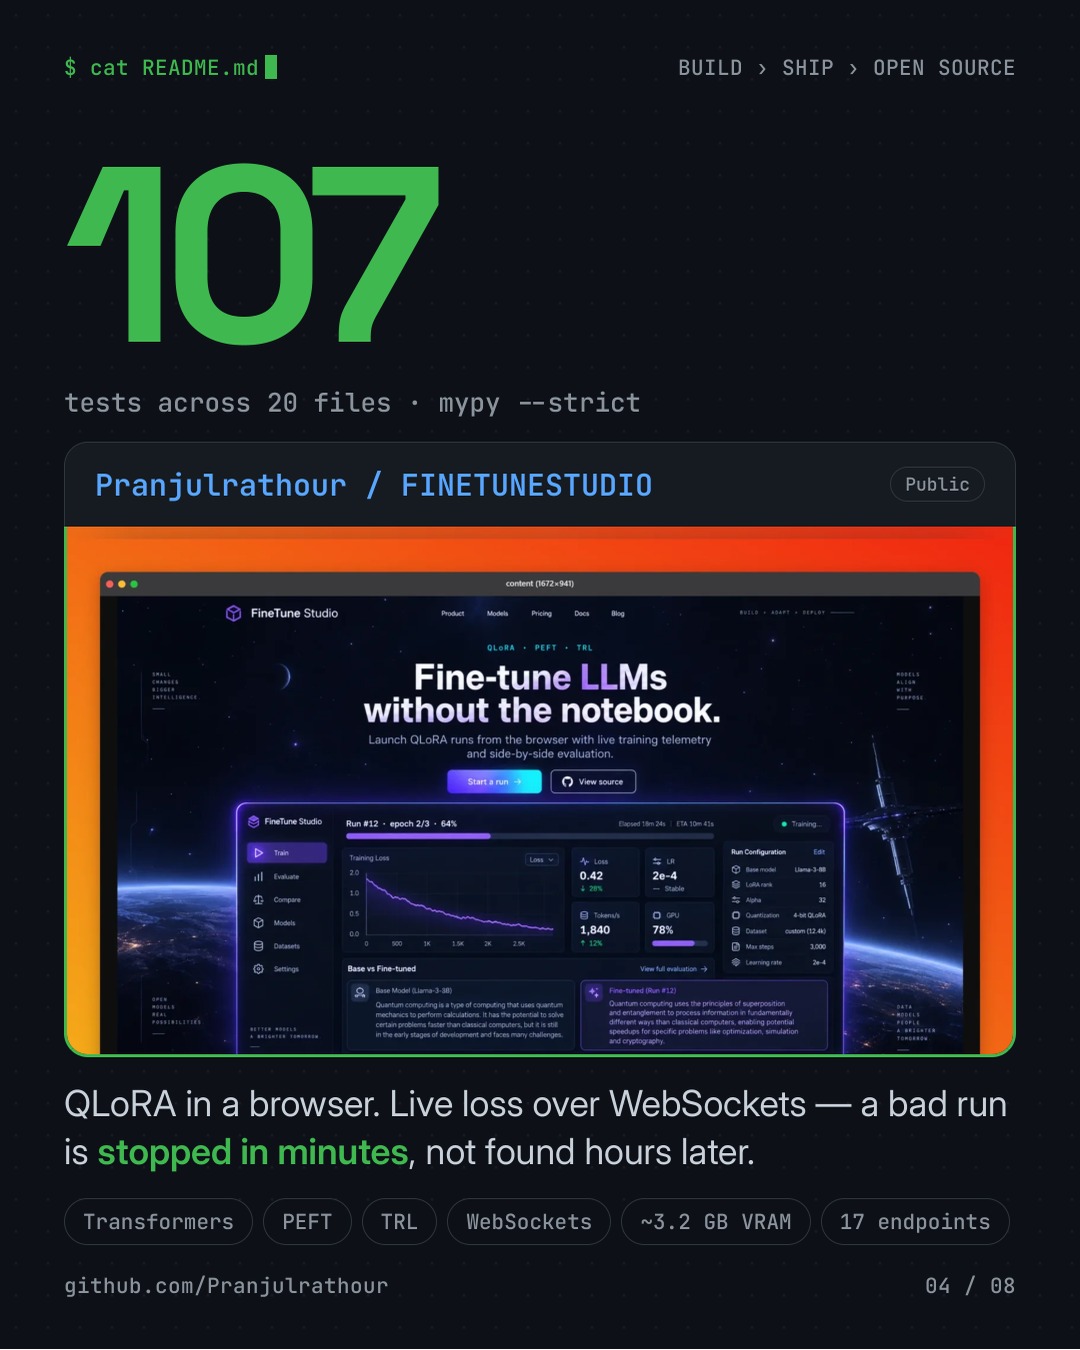
I built FineTune Studio after making most of these mistakes on my own runs. They are not exotic. They are the difference between "I fine-tuned a model" on a resume and "I fine-tuned a model and here is what improved by how much".
The mistakes
- No baseline. Not running the base model on the same evaluation set first. Without it, you cannot know whether the fine-tune did anything. Base-versus-tuned is the whole point.
- Training on unvalidated data. Malformed records, duplicates, and template mismatches. Run the pre-training checklist first.
- Leaking eval into training. Splitting after deduplication is not optional.
- Chasing training loss. It goes down whether or not the model is getting better. Watch eval loss, then read outputs.
- Too many epochs on too little data. A few hundred examples for ten epochs is memorisation with a progress bar.
- Choosing the biggest model that fits. A 1–3B model fine-tuned well beats a 7B model fine-tuned badly, and ships on hardware you have.
- Fine-tuning for facts. Knowledge belongs in retrieval; see RAG vs fine-tuning.
- Ignoring the chat template. Training with one format and serving with another produces a model that seems to have forgotten everything.
- Not saving checkpoints. The best model was at step 600; you only kept step 1200.
- No deployment plan. An adapter on a laptop is not a result anyone else can use. Decide how it will be served before you start.
The habit that prevents most of them
Write the evaluation before the training script: the held-out set, the rubric, and the baseline numbers. Everything else becomes an experiment against a fixed target instead of a hope. That habit, more than any hyperparameter, is what I try to teach in campus sessions on fine-tuning.
Make these mistakes once, on a small model, on a weekend. Then never again.
At an Integral Startup Foundation hackathon
Pranjul Rathour
 | Pranjul Rathour GenAI engineer, Kanpur · 3x first-prize hackathon winner · campus mentor I ship production RAG pipelines, fine-tune LLMs and build agentic AI products end to end. I lead engineering at SCULT INDIA for a 14-member team and have mentored 200+ students through TechVerse Enclave. Open to: GenAI roles, hackathon judging, mentorship sessions and guest talks at colleges. Email: pranjulrathour41@gmail.com |
On stage, at hackathons and on campus
 Presenting to a room |  Pranjul Rathour |  Pranjul Rathour, GenAI engineer, Kanpur |


Comments
Post a Comment