How to evaluate a RAG system: recall, faithfulness and the questions that matter
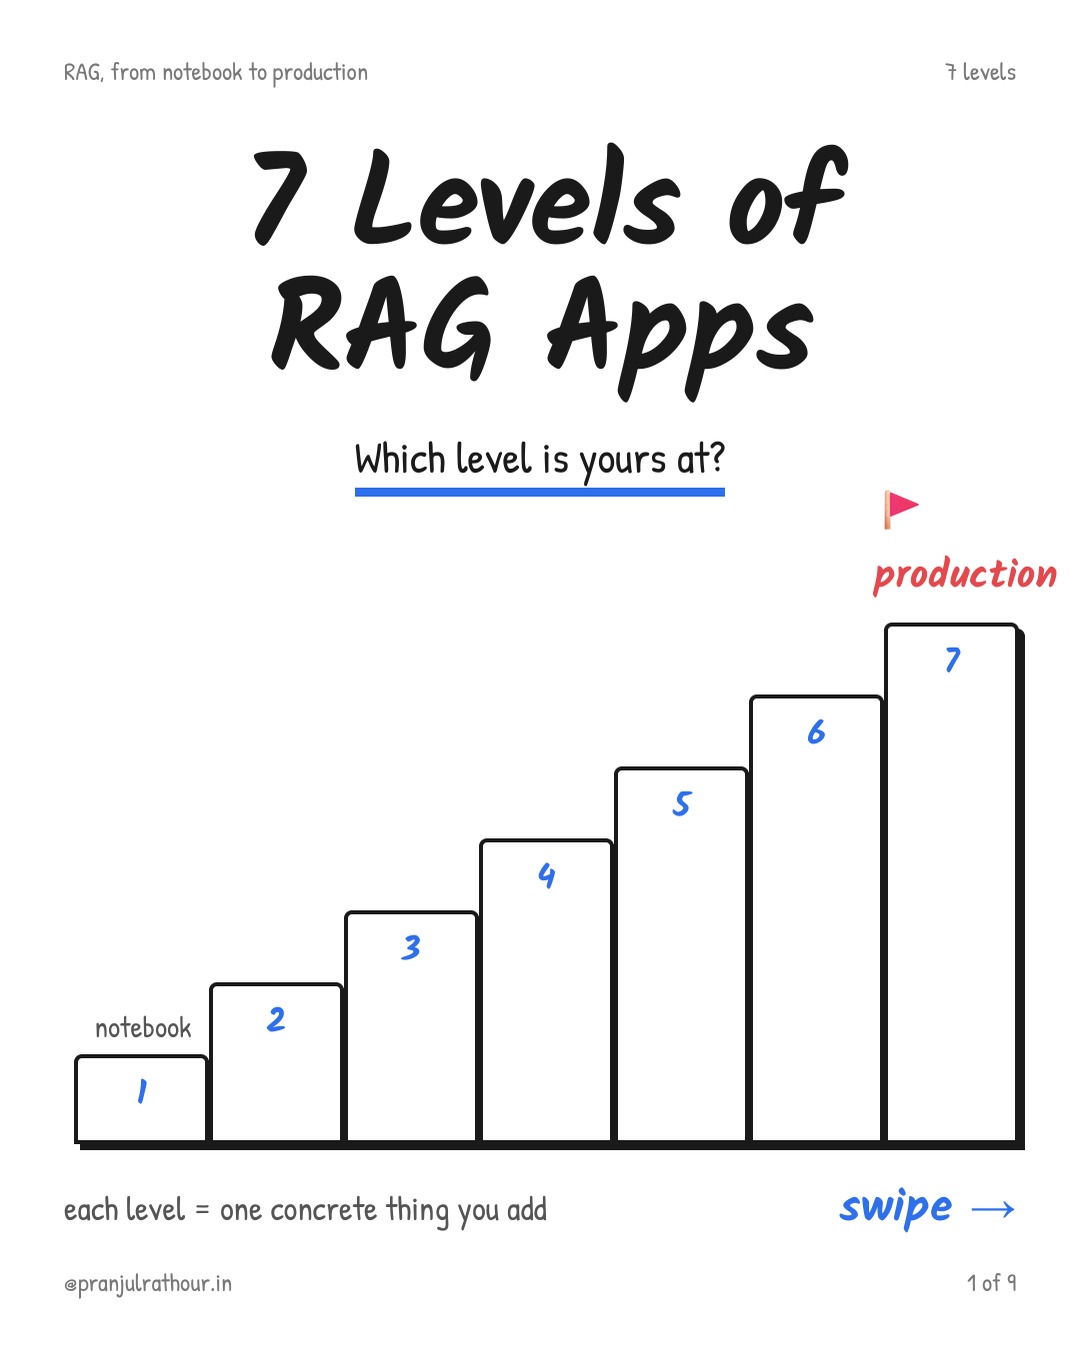
Originally published at https://pranjulrathour.scult.in/blog/rag-evaluation-metrics-faithfulness-recall. That copy is the canonical version and gets updates first.
You cannot improve a RAG system you are not measuring, and "I asked it five questions and it seemed fine" is not measuring. Every serious change I made to RAG.NextUpgrad — hybrid search, reranking, the confidence gate — was justified by a number moving on a fixed evaluation set. Here is the setup, sized for a student or a small team.
Build the question set first
Collect 50 to 100 real questions. For each, record the passage (and page) that answers it, and the expected answer in one sentence. Include 10 to 20 questions the documents cannot answer — those test whether the system refuses correctly. This set is your most valuable asset; version it alongside the code.
Four metrics, in order of importance
- Retrieval recall@k — is the correct passage among the top k retrieved? If this is low, nothing downstream can save you. Fix chunking and retrieval before anything else.
- Faithfulness — does every claim in the answer appear in the retrieved context? Grade it with a rubric, by hand for the first hundred answers and with an LLM judge afterwards, spot-checking the judge.
- Refusal accuracy — on unanswerable questions, does the system say it does not know? On answerable ones, does it avoid refusing? A confidence gate is tuned entirely on this metric.
- Answer correctness — does the answer match the expected one? Useful, but it hides whether a correct answer came from the documents or from the model's memory.
A minimal evaluation loop
Run the set on every change — a script that indexes, queries, and writes a CSV is enough. Track recall@5, faithfulness rate, false-refusal rate and false-answer rate over time. When a change improves one metric and hurts another, you have a real decision to make instead of an argument.
Traps I fell into
- Writing questions by reading the documents, which produces questions phrased exactly like the text. Real users paraphrase; add paraphrased versions.
- Grading with the same model that generated the answer, without checking the judge. Judges are lenient on fluent prose.
- Evaluating only happy-path questions. The refusal set is where a production system earns trust.
A confidence gate without an evaluation set is a guess with a threshold. With one, it becomes the most defensible feature in the product — I explain the gate itself in why my RAG platform says "I don't know".
 | Pranjul Rathour GenAI engineer, Kanpur · 3x first-prize hackathon winner · campus mentor I ship production RAG pipelines, fine-tune LLMs and build agentic AI products end to end. I lead engineering at SCULT INDIA for a 14-member team and have mentored 200+ students through TechVerse Enclave. Open to: GenAI roles, hackathon judging, mentorship sessions and guest talks at colleges. Email: pranjulrathour41@gmail.com |
 Pranjul Rathour |  Pranjul Rathour, GenAI engineer, Kanpur |  In a packed college auditorium |


Comments
Post a Comment