Chunking strategies for RAG: sizes, overlap and structure-aware splits
Originally published at https://pranjulrathour.scult.in/blog/rag-chunking-strategies-guide. That copy is the canonical version and gets updates first.
Most RAG quality problems I have debugged were chunking problems wearing a disguise. The model looked like it was hallucinating; the retriever was actually handing it half a table, or a paragraph whose subject lived in the previous chunk. Before you tune prompts or switch models, look at what your chunks actually contain.
Three rules that survive every project
- Chunk for the question, not the document. A chunk should be able to answer a realistic user question on its own. For policy documents that is often 300–500 tokens; for API references it can be a single function signature plus its description.
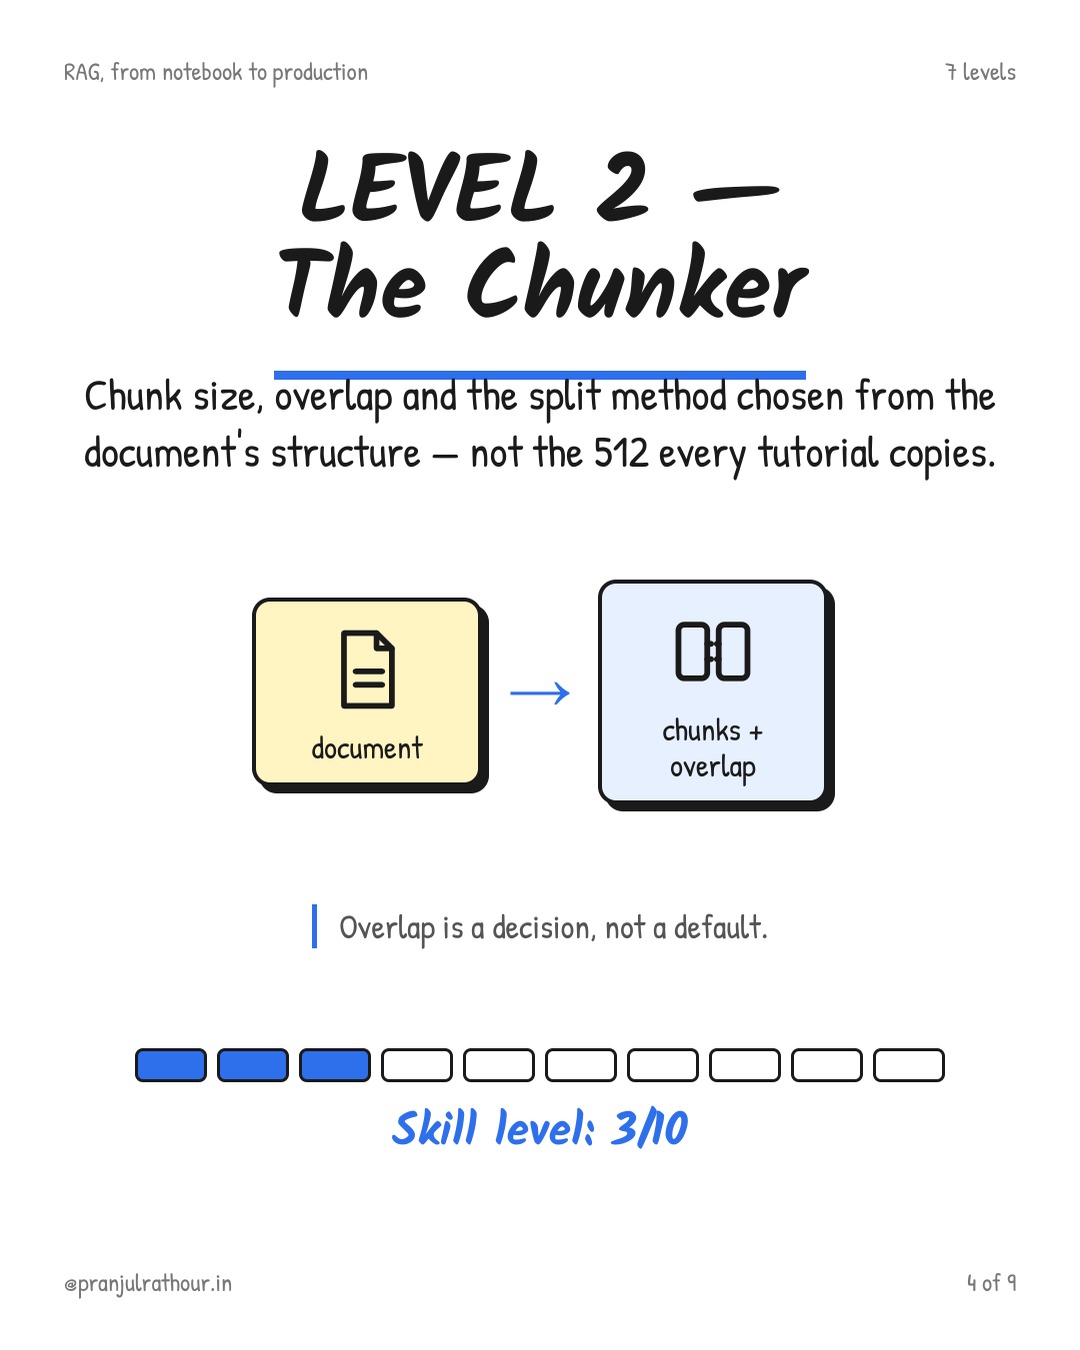
- Overlap is insurance, not a strategy. 10–15% overlap catches sentences that straddle a boundary. Larger overlaps mostly duplicate what the reranker sees and inflate your index.
- Never split inside a structure. Tables, code blocks, numbered procedures and headings with their first paragraph belong together. Splitting them produces chunks that are individually meaningless.
Structure-aware splitting in practice
In RAG.NextUpgrad the ingest step first detects structure — headings, list runs, table rows — and only then applies a size budget. A heading is prepended to every chunk beneath it, so a chunk that says "the limit is 5 requests per second" also carries "Section 4.2: Rate limits". That single trick did more for answer accuracy than any embedding model change.
For scanned PDFs, run OCR page by page and keep page numbers as metadata. In the OCR & Speech Workspace every chunk records its page, which is what makes citations like "page 14" possible in the answer.
How to pick a size without guessing
Build a small evaluation set first: 30–50 real questions with the passage that answers each. Index the corpus at three chunk sizes (say 256, 512 and 1024 tokens), run the questions, and measure how often the correct passage appears in the top 5. The size that wins on recall is your starting point; then check answer quality, because a chunk that retrieves well can still be too fragmentary to answer from.
Signs your chunking is wrong
- Answers that are correct but cite the wrong section — the heading context is missing.
- Numbers quoted without their unit or condition — a table was split across chunks.
- The model says "the document does not specify" for facts you know are there — the fact straddles a boundary and neither half ranks.
- Retrieval scores are uniformly high — chunks are so large that everything looks relevant.
Chunking is unglamorous, and it is the first thing I check when a student shows me a RAG demo that "sometimes works". Fix the chunks and the rest of the pipeline suddenly looks smarter than it is.
 | Pranjul Rathour GenAI engineer, Kanpur · 3x first-prize hackathon winner · campus mentor I ship production RAG pipelines, fine-tune LLMs and build agentic AI products end to end. I lead engineering at SCULT INDIA for a 14-member team and have mentored 200+ students through TechVerse Enclave. Open to: GenAI roles, hackathon judging, mentorship sessions and guest talks at colleges. Email: pranjulrathour41@gmail.com |
 Pranjul Rathour, GenAI engineer, Kanpur |  In a packed college auditorium |  Pranjul Rathour |


Comments
Post a Comment